
Summary: An enterprise DAM should return keyword and metadata search results in under one second, even across a library of millions of assets. Filtering and refining should feel instant, at about 0.1 seconds, and AI, natural language or visual similarity search should come in close to one second. These targets are based on response-time research. When you evaluate vendors, ask for 95th-percentile response times under realistic peak load, then test with your own content, queries and permission profiles.
Every DAM vendor says its search is fast, and in a demo with a few thousand clean sample files, most of them are. The harder question is what happens when hundreds of people search a library of millions of assets at the same time, with permissions, rights and AI-generated tags and transcripts all in play.
Speed matters more than it seems. In a 2024 update to his response-time research, Jakob Nielsen notes that people only feel free to move through a site when it responds in under one second, and they visit fewer pages when it's slower. In a DAM, where adoption depends on people finding assets quickly, slow search means less of the library gets used.
The most useful benchmarks available come from research on how people respond to wait times. That research shows how fast search needs to be for people to keep coming back to the DAM. Here's how those findings translate into targets for each type of search, and how to test them during your evaluation.
Why does search speed matter in an enterprise DAM?
Search speed decides whether people use the DAM or work around it. Nielsen Norman Group research shows that once a response stretches past one second, people feel like they're waiting on the technology and explore less freely.
That exploration is where a DAM earns its value. Many organizations hold valuable assets users haven't discovered yet, and slow search makes them harder to find. In a 2026 Forrester study commissioned by Orange Logic, 62% of DAM decision-makers said they're overwhelmed and unable to make full use of their digital assets. Sixty-nine percent said they need more AI-powered search and discovery to help with rapid access.
What search response times should you expect from an enterprise DAM?
An enterprise DAM should return standard search results in under one second, even across your full library. The targets below map common search actions to the response-time limits that shape user behavior.
|
Search action |
Target response time |
Why this target |
|---|---|---|
|
Typing, filtering and refining results |
About 0.1 seconds |
At this speed, users feel they're directly controlling the results. |
|
Keyword or metadata search |
Under 1 second |
Users stay in their flow and keep refining. |
|
Natural language, AI or visual similarity search |
Close to 1 second |
AI search interprets intent, which adds processing. Past a few seconds, users stop exploring. |
|
Loading previews and jumping to a moment in a video |
As fast as the results themselves |
Users judge results by previews, so slow previews slow the whole search. |
|
Searches through APIs and integrations |
Same as the interface, under peak load |
Portals, plugins and AI agents all search the same index as your users. |
These targets are recommendations based on Nielsen's response-time research, since no published DAM benchmark exists. When you ask vendors for numbers, request 95th-percentile response times measured under realistic load, not averages or best-case results. An average hides the slow searches users remember.
What slows DAM search down at enterprise scale?
DAM search slows down when the library, the user base and the rules applied to each result all grow at once. A platform that feels fast in a pilot can lag once these factors stack up.
- Library growth. Every search has to cover more assets as the library grows, and many teams are already planning for growth. In the Orange Logic commissioned Forrester study, 75% of respondents expect their rich-media requirements to increase.
- Concurrent traffic. Every user, portal, integration and AI agent sends queries to the same search engine. At peak times, that load can slow results for everyone unless the platform scales to handle it.
- Permission and rights checks. Before results appear, each one has to be checked against what that specific user is allowed to see and use, which adds work to every query. The more detailed the permission rules, the more checking each search requires.
- Rich media enrichment. Transcripts, OCR text, face data and AI tags make assets more findable but also add more data to search through.
How do you test DAM search performance during an evaluation?
The most reliable test uses your own content, your own queries and realistic user profiles. To see how a platform performs before you commit, build these steps into your proof of concept or scripted demo.
- Load a real sample of your library. Include video, large files and assets with inconsistent metadata. A sample won't show speed at full scale, but it shows whether search finds the right assets across your real file types and metadata.
- Write 15 to 20 real queries from different teams. Mix exact searches (a SKU or file name) with natural language requests like "approved product photos from the spring campaign." If you'll rely on visual similarity search, test it with your own images too, since quality varies widely between platforms. A strong platform returns the asset you wanted on the first screen of results for most queries, within the response times in the table above.
- Search with real permission profiles. Log in as an agency partner or regional marketer, since filtered searches are where slowdowns often appear. Their searches should return about as fast as an admin's and show only the assets that user is allowed to see.
- Ask for proof under load. Request performance data for the peak number of people you expect to be searching at once and the library size you expect in three years, plus a customer reference with a library similar to yours.
- Time the whole task. Measure from the first query to the moment someone has the right asset, and count how many refinements it took. This number runs longer than a single search's response time, so you're not measuring fractions of a second, and it shows whether fast results are also the right ones. There's no standard target, so compare each platform on the same queries, and against how long the same tasks take in your current system.
- Repeat at different times. Run the same queries on different days, including a busy weekday morning and a quiet afternoon. Response times should stay close to each other and the same assets should appear near the top each time. If speed swings widely, ask the vendor what causes it, since users notice the slow searches more than the fast ones.
What does fast search look like at enterprise scale?
Fast search at enterprise scale should feel the same with 50 million assets as it did with 50,000. Results come back in under a second whether someone types a file name, describes a scene or drops in an image, and each person sees only what they're allowed to use.
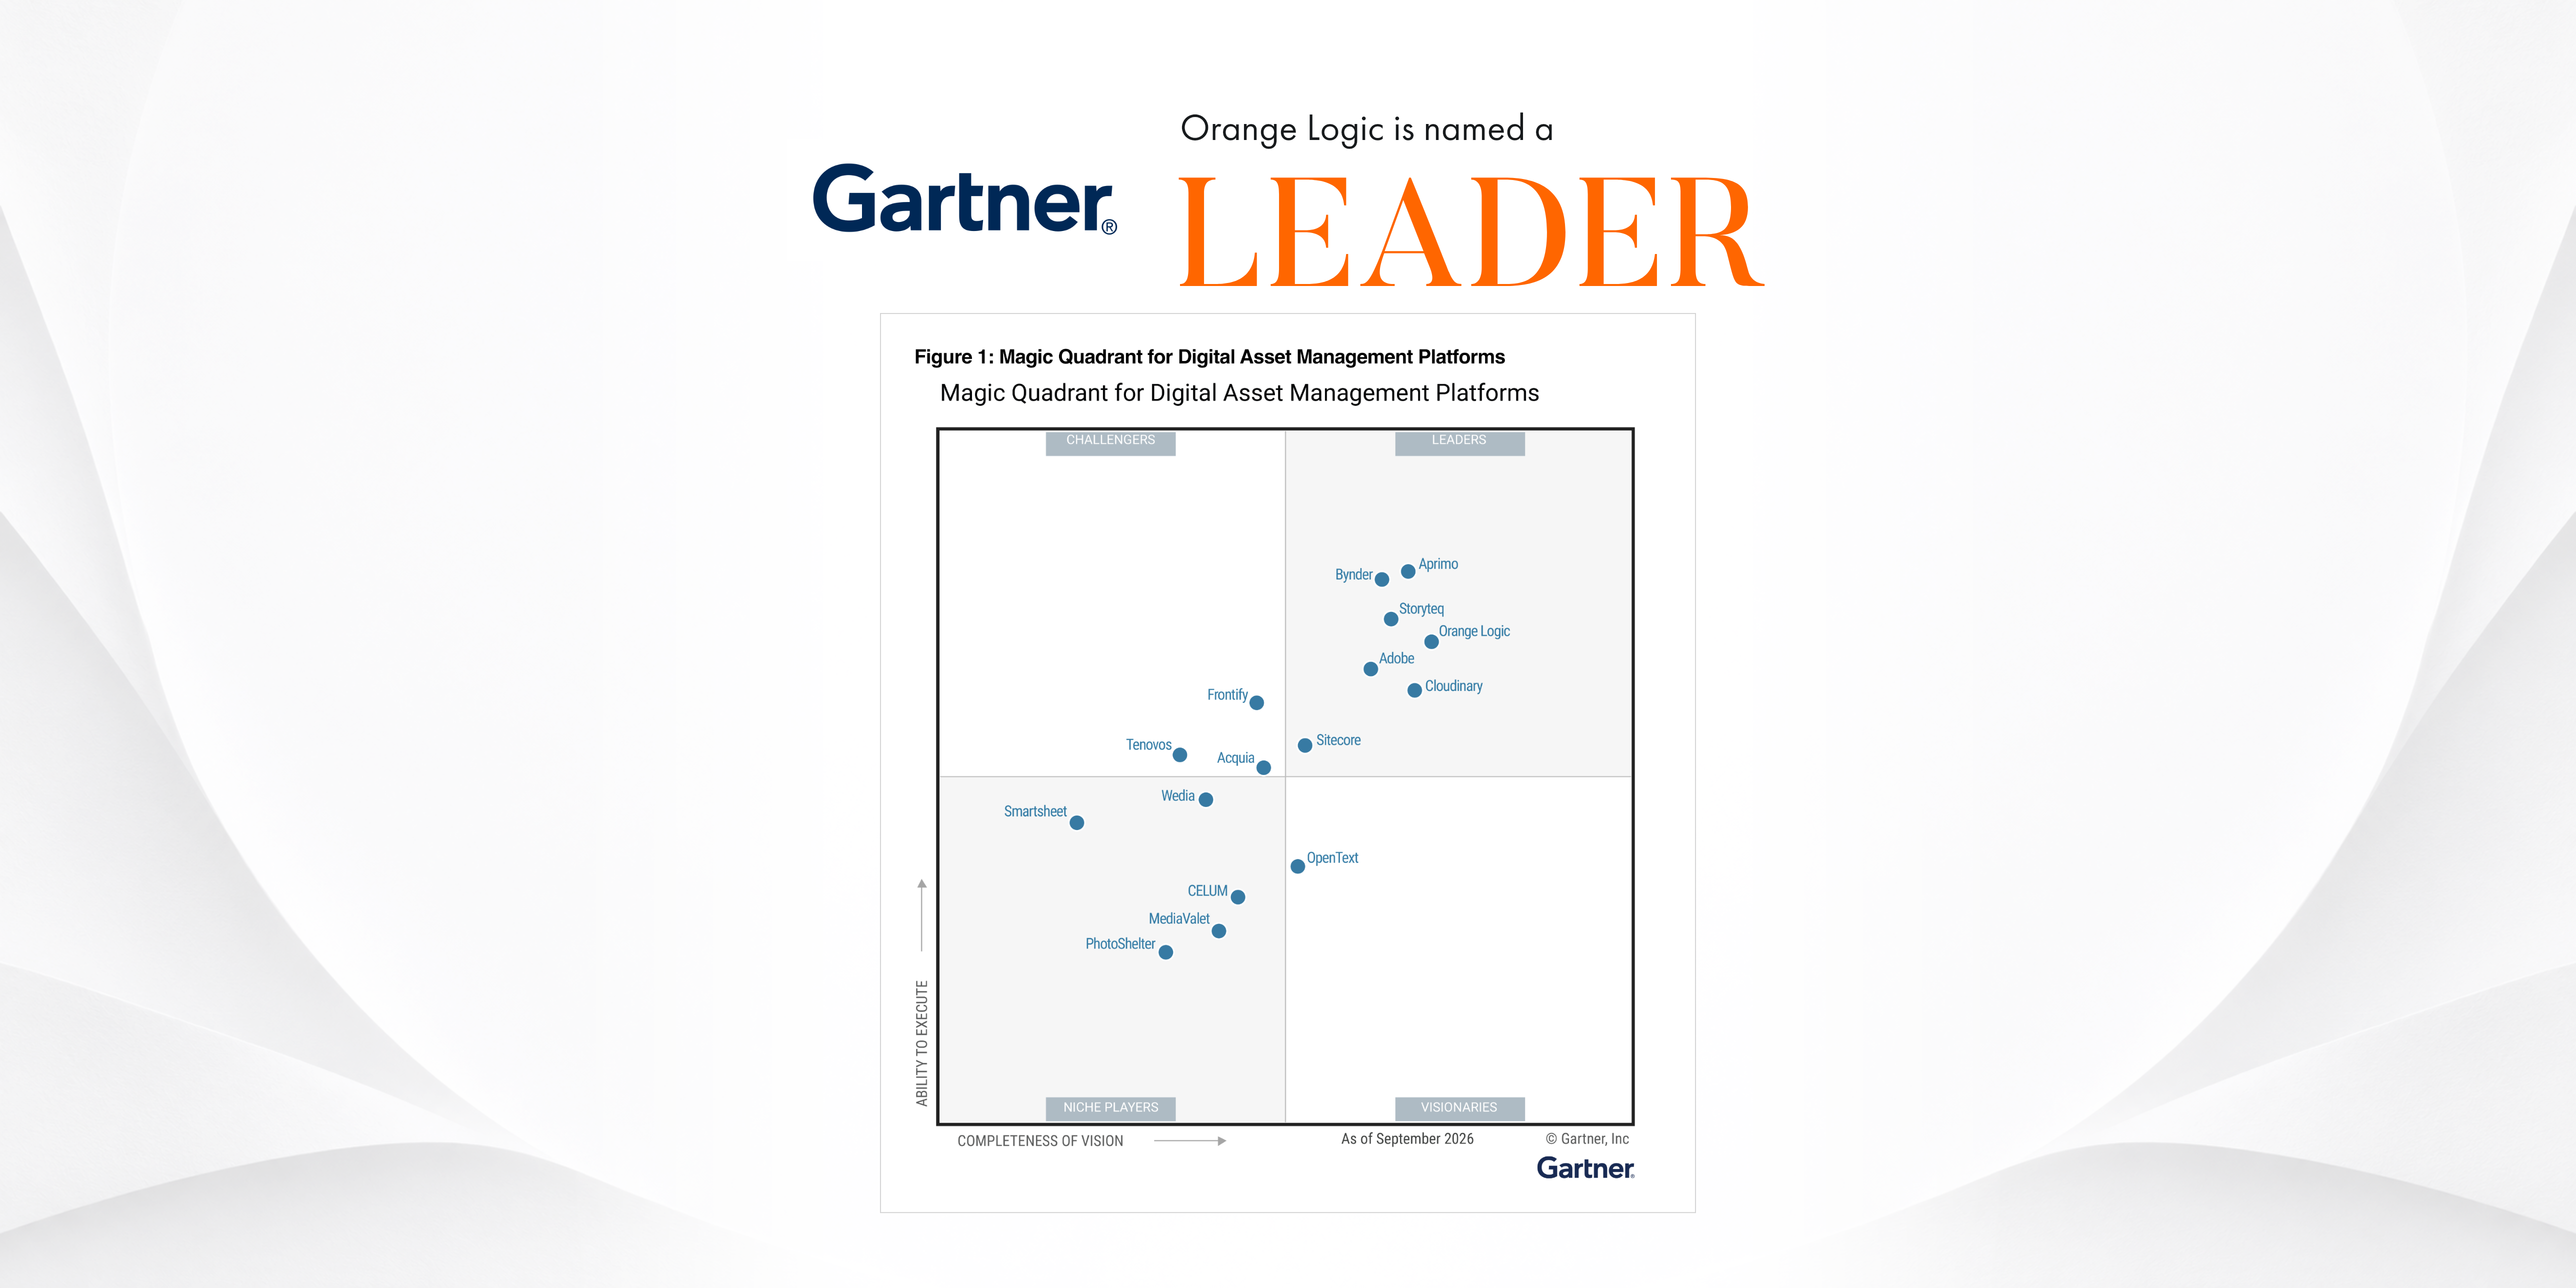
For instance, Orange Logic search covers metadata and natural language, plus what's inside images, video and documents. The Forrester Wave™: Digital Asset Management Systems, Q1 2026 found that its multi-engine approach "delivers subsecond response times across libraries," even for Orange Logic customers who run libraries of tens of millions of assets and petabytes of data.
Those response times already include permission and rights checks, which are a common source of slowdowns. The same applies to searches run from AI tools through Orange Logic's MCP server, which return the same results a user would see in the Orange Logic interface. Video search saves time after the results load, too, jumping straight to the moment a tag, phrase or person appears so no one has to scrub through hours of footage.
Pearson shows what that looks like under heavy load. The education company manages more than a million assets in Orange Logic and scaled to 40,000 API calls a minute to serve educational videos, using a cached CDN layer that cuts latency for repeat views. "We've increased the effectiveness of our search, gained insight on our actual usage, and reduced our costs by 30%," said Kyrce Swenson of Pearson.
Test subsecond search on your own library
See how Orange Logic's search and discovery tools perform on your own content.